Small Language Models Beat GPT for Document Classification
Should you use a small language model or GPT for document classification? For almost any production routing, triage, or tagging workload, a fine-tuned 400M-parameter encoder beats the frontier API on cost, latency, and often accuracy.
The token math behind that claim, what encoders like DistilBERT and ModernBERT actually do well, a reference deployment that runs on a single GPU, and the narrow cases where a general-purpose LLM is still the right call are all covered below.
The Cost Math Turns on Volume
A frontier API call on a 2,000-token document costs on the order of a fraction of a cent. That figure is fine in a demo and painful in production. Classify a hundred thousand contracts a month and the per-token model wears through its own business case.
Fine-tuned encoders invert the math. The training run is a fixed cost, inference burns watts on commodity hardware, and a single 24GB GPU can host several specialized classifiers for different routing tasks. NVIDIA Research argued in a 2025 position paper that small models under 10B parameters are not just adequate but inherently better suited for scoped, repetitive subtasks. Document classification is the textbook example: a fixed label set, bounded input, no conversational turn.
The LoRA Land technical report evaluated 310 fine-tuned small LLMs across 31 tasks and found 4-bit LoRA adapters beat their base models by 34 points and GPT-4 by 10 points on average. Twenty-five of those fine-tuned Mistral-7B variants ran simultaneously on one NVIDIA A100.
The usual counter — "we do not want to manage GPUs" — is a staffing question, not a cost one. Our breakdown of private vs proprietary AI token math walks through where the crossover actually sits.
What a 400M Encoder Actually Does for Classification
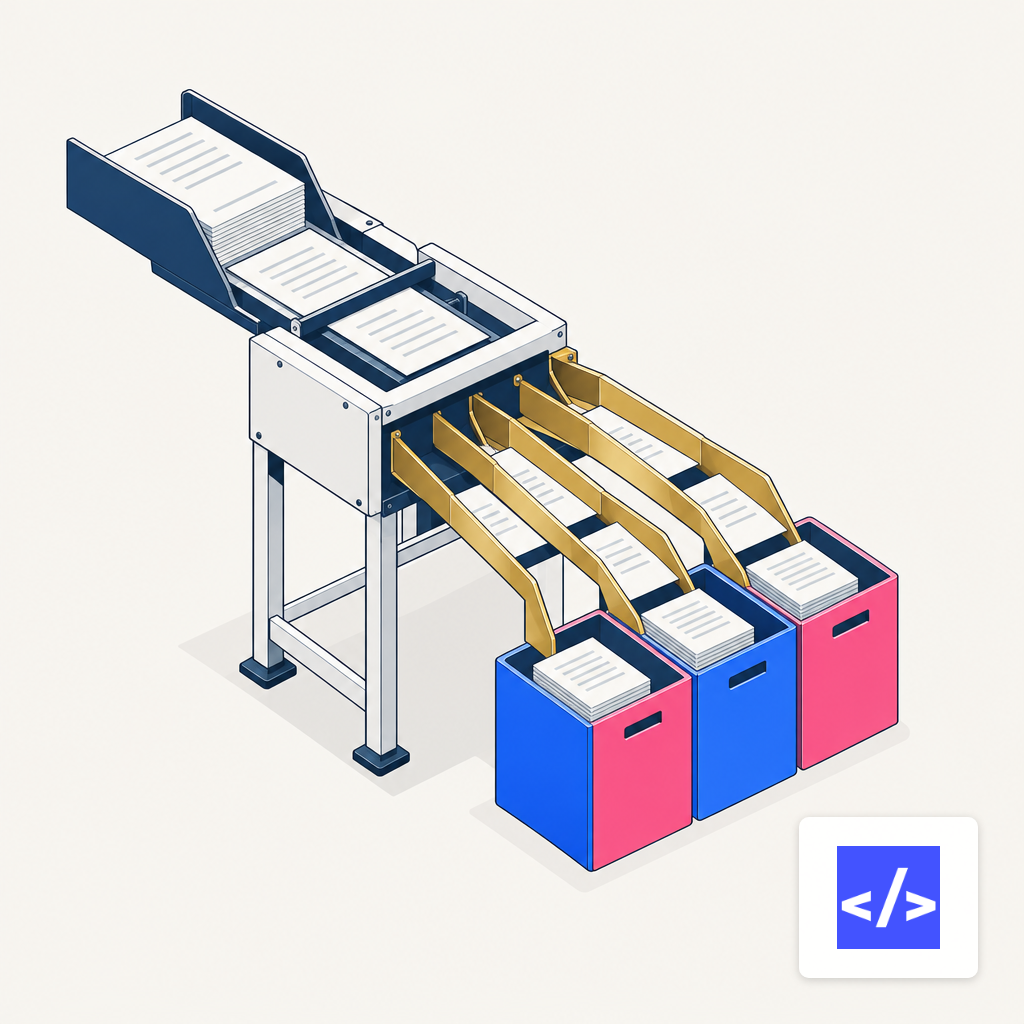
DistilBERT (66M parameters), BERT-base (110M), and ModernBERT (139M to 395M) are encoder-only Transformers. Given a document, they emit logits over a fixed label set in a single forward pass. No sampling, no decoding loop, no autoregressive generation.
That shape matters for three reasons:
- Bidirectional attention reads the entire document at once, which is the natural shape of classification rather than left-to-right next-token prediction.
- Latency is predictable because there is no generation loop. A single inference on a modern CPU typically finishes in tens of milliseconds.
- The output is a probability vector, not prose, so the parse-the-LLM-response layer that eats engineering time in LLM pipelines simply disappears.
Supervised sequence classification was mostly solved before GPT-4 existed. It stayed solved. The capability lead on open-ended generation does not transfer to a job where the taxonomy is yours and the input has a known structure.
General Benchmarks Do Not Settle a Classification Question
Phi-4 trades wins and losses with GPT-4o across the standard benchmark suite. It beats GPT-4o on graduate-level science questions and mathematical reasoning, and loses on general knowledge, code generation, and factual recall. The deltas are worth seeing in one picture.
None of those scores measure how well either model will route your invoices or triage your support tickets. Benchmark deltas are a useful filter for general-purpose work. For a narrow classification taxonomy, only a labeled holdout from your own corpus settles the vendor question, and a few thousand examples usually settle it against the fine-tuned encoder.
A Reference Architecture That Runs on One GPU
A production document routing system does not need a model marketplace. The parts list is short:
- A base encoder: DistilBERT or BERT-base for short documents, ModernBERT where sequences exceed 2,000 tokens (it supports 8K).
- A labeled dataset of 5,000 to 20,000 examples per class, usually bootstrapped by running a frontier LLM over the backlog and correcting the obvious errors.
- A fine-tuning run on a single NVIDIA L4 or A10G, typically under an hour per class head.
- Serving on one GPU through vLLM, TGI, or TorchServe, or a CPU pool for routing volumes under a few requests per second.
- Monitoring on class confidence and drift, with a human-in-loop queue for low-confidence predictions.
For regulated environments, the whole stack fits inside a VPC or a fully offline host. The hardware economics of that choice are covered in our piece on AI workloads moving back to on-prem. Our AI development services team sizes these deployments every month.
Where the SLM Market Is Already Pricing This In
The small language model market was valued at $7.8 billion in 2023 and is projected to reach $11.1 billion in 2026 and $20.7 billion by 2030. The interesting cut is not the total but the segmentation.
Conversational AI still leads revenue, but the document-shaped slice — data extraction and document analysis — already makes up roughly 12% of 2025 SLM spend. That is the exact workload this article argues against routing through a per-token frontier API.
When a Frontier LLM Still Earns Its Slot
Not every document job belongs on a fine-tuned encoder. A frontier model is still the right call for:
- Open-ended extraction where the schema is genuinely unknown or shifts week to week.
- Low-volume, high-value documents (a hundred M&A memos a quarter) where the labeling investment would never clear.
- Mixed tasks where a summary and a routing decision come out of the same call, and running two systems would exceed any savings from the smaller one.
- Early prototypes that need to validate the taxonomy before the labeling budget gets spent.
The pattern mirrors production RAG cost planning: the right model is often the smaller one, and the exception proves the rule rather than disproving it.
Three situations, three next steps.
Already running document classification through a frontier API: pull the last 30 days of volume and multiply by per-call cost. If the figure crosses a few thousand dollars a month and the label set is stable, a labeled-data audit and a DistilBERT fine-tune usually pay for themselves inside a quarter.
Building a new document pipeline from scratch: use a frontier model to validate the taxonomy on the first few hundred documents, then label 5,000 examples and distill into an encoder before production. The frontier model becomes a labeling tool, not a dependency.
Unsure whether volume justifies the engineering: price a six-month encoder deployment against projected API spend at realistic growth. The break-even is almost always clearer than it looks from inside the token budget.